12x
more tokens
Without security context, agents re-derive reachability every time. An unaided agent used 79.5M tokens; with Endor Labs evidence, the same model used 6.6M.

Harness Your Mechs
Every growing codebase forest has hidden sinkholes.
A security engineer builds an agent that reviews PRs and drafts fixes. Then platform engineering asks to run it across all 2,000 repos, and three costs compound.
12x
Without security context, agents re-derive reachability every time. An unaided agent used 79.5M tokens; with Endor Labs evidence, the same model used 6.6M.
44%
Review and verification make up about 59% of agent token spend. Comcast found 44% of validated critical and high-severity AI findings were false positives.
63%
The top agent on the Agent Security League hits 87% functional correctness, but most of its working code still isn’t secure.
Finding a potential vulnerability creates work before it produces a security outcome.
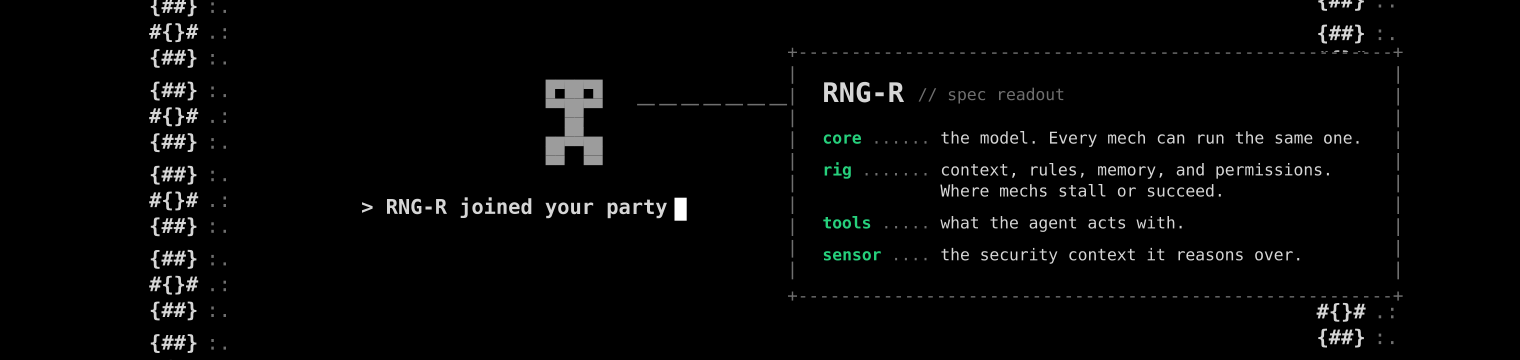
Model your token costs> RNG-R joined your party
Inspect your mechs before the journey ahead
None of this means teams shouldn't build. It means deciding which layers your team builds, which capabilities your agents call, and what belongs in the harness around the model. Every security agent has the same anatomy.

Your policies (what your team considers acceptable), risk tolerance (which services matter most), and workflows (how findings get triaged and fixed). That’s where your team’s hard-won knowledge lives, and no vendor can ship it in a box.
The foundation underneath: context (how your code actually behaves), verification (confirmation a finding is real), evidence (a chain you can walk an auditor through), and economics (costs that stay predictable as volume grows).
You, InfoSec / Eng leader
Vuln discovery agent
Validate & triage agent
Remediation agent
Yes, it's a metaphor. Read the full story in Once upon the codebase forest.
Navigate the depths of the codebase forest
Most AppSec teams don’t lack ambition. They lack a roadmap. Here’s what each level takes, and how to build what’s yours so it holds up at scale.
Developers use approved coding agents under company accounts, you know every agent, model, MCP server, and skill in use, and security guidance reaches agents as code is written. Mostly buy; what you build is policy. With AURI: Coding Agent Governance.
Install now
Purpose-built agents find, verify, triage, and fix vulnerabilities, with evidence that each finding is real and reachable, and people approve what they propose. Mostly buy; what you build is routing and merge policy. With AURI: AI SAST and SCA with Reachability.
Book a demo Your team builds skills that encode how you do one security task, like your triage rules or threat model, each with an eval suite and an owner. Both: build the skills, buy the context they call. With AURI: AURI Agents and the code context graph.
Learn more Specialized agents work as a system, acting on events within limits you set, and each earns its autonomy one action at a time. Both: build the orchestration and autonomy gates, buy the foundation they call. With AURI: the code context graph.
Learn more 
Learn how to build and scale AI to secure your codebase, fix vulnerabilities, and generate secure code by default.
What to look for in an applied AI partner
Not every approach to AI in AppSec can take you from prototype to production. Whether you build, buy, or both, here are the questions worth asking and what a good answer looks like. Hold us to them too.
Look for: Published benchmarks with full methods and reproducible setups, including where they lost, not just a headline number.
Look for: A precision rate you can measure yourself, and evidence behind every finding: reachability, data flow, and exploitability.
Look for: Checks as agents write code, plus agents that find, triage, and fix across your codebase, with people approving what they propose.
Look for: Named engineers who help with architecture and deployment, not a handoff to a support queue.
How Endor Labs secures your agentic SDLC
We're an applied AI lab for software security. We do the research, show our work, and work alongside your team until it runs at scale.
A level-by-level path for architecting security into the agentic SDLC, including what to build and what to buy.
We measure what agents actually cost and catch, then publish the methods, including results where we don’t come out on top.
Architecture and deployment support from engineers who work alongside your team, not a handoff after the contract is signed.
The foundation at every level, giving your agents verified security context to find what’s real and fix it at a predictable cost.
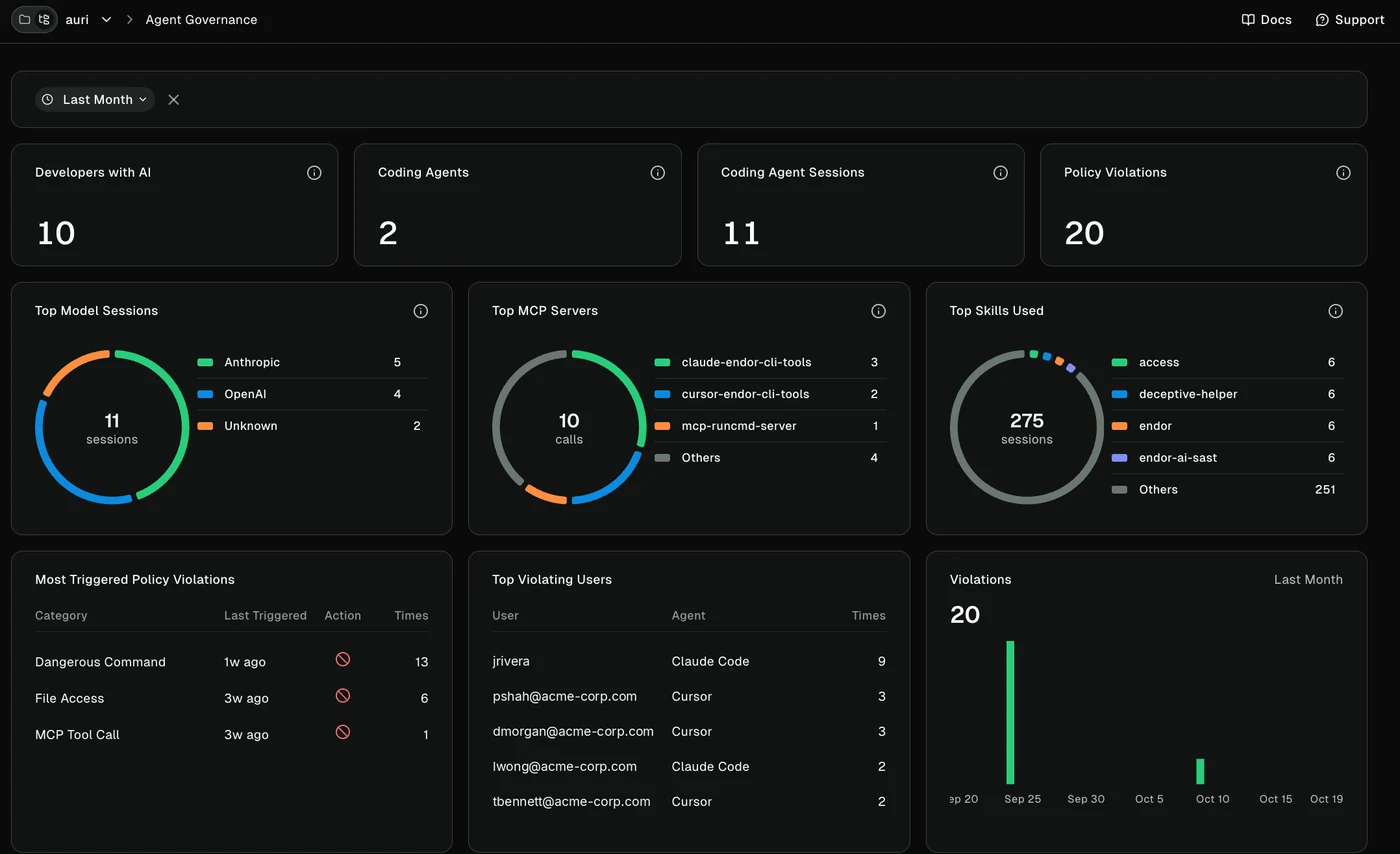
At Level 1, inventory every coding agent, MCP server, and skill, enforce policy through hooks, and check code as it’s written with AURI for Developers.
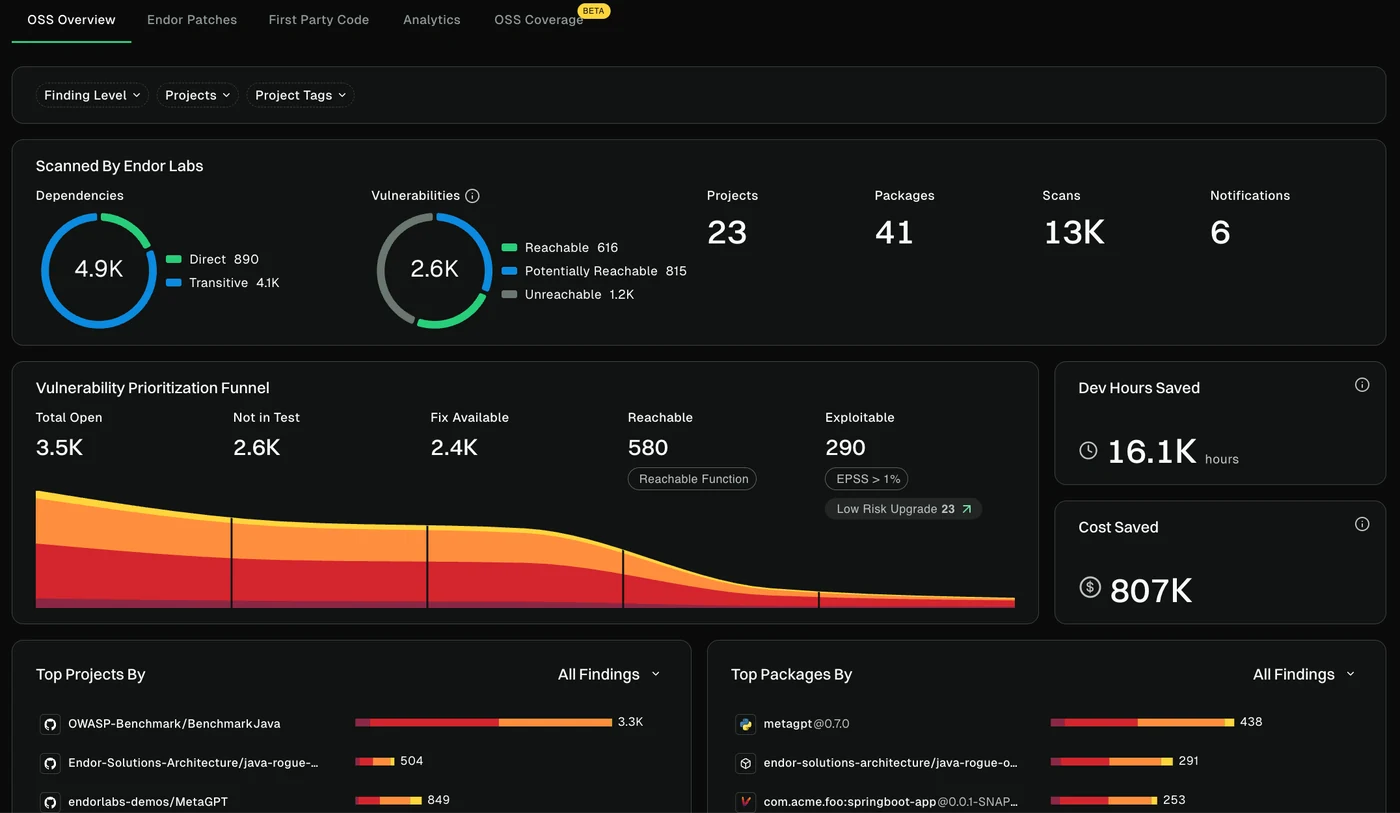
At Level 2, AI SAST combines agentic reasoning and deterministic tools to catch complex logic flaws, and reachability-based SCA reduces false positives by 92%.
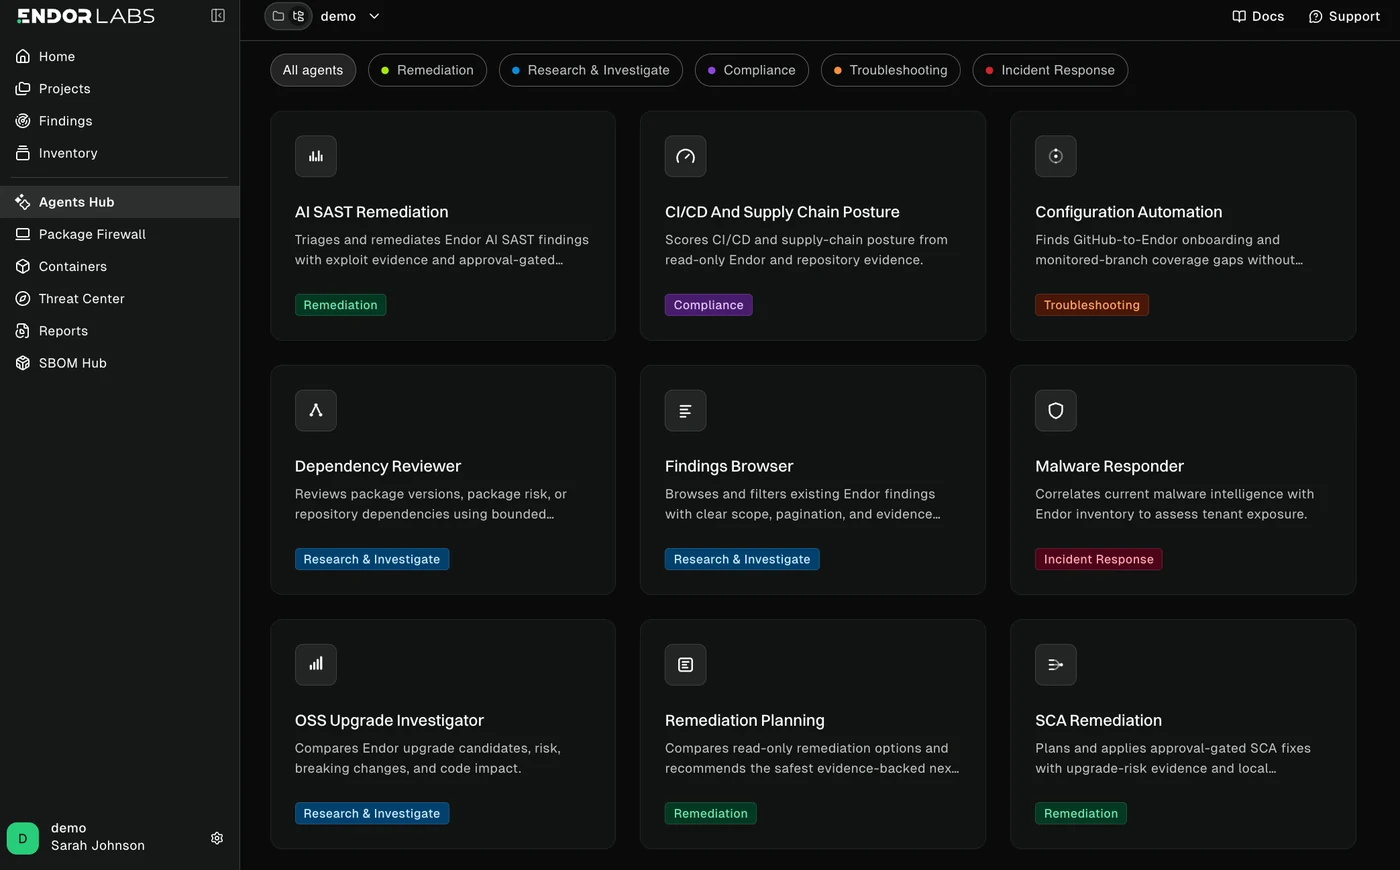
At Levels 3 and 4, build custom security agents leveraging AURI context, tools, and data, or start from 11+ open source agents, then run them as one system.
Underneath every level, AURI’s code context graph continuously models your code, dependencies, and containers, and your agents reach it through MCP, skills, hooks, CLI, and API.
See AURI live on Dec. 2Benchmarks and customer results
We continuously benchmark the latest agents and models, and publish everything for you.
6.6M vs. 79.5M tokens across 34 security prompts, and 133 vs. 370 minutes. See Token Economics report.
Than Claude Opus 4.7 in an 8-project benchmark, including 63 found by no other tool. AI SAST benchmark.
Under a minute, vs. 18 to 20 minutes for Claude Code Security.
Token spend varies 1.8x across projects with Endor Labs evidence, vs. 4x without. See Token Economics report.
A real zero-day in Anthropic's buffa library, found through data-flow analysis.
With function-level reachability across 40+ languages.
It started with cutting SCA noise in Grok Build’s own codebase. Now Endor Labs checks the tools, code, and dependencies agents touch in every Grok Build session.

It started with cutting SCA noise in Grok Build’s own codebase. Now Endor Labs secures every agent session on Grok Build.”
 Travis McPeak Security @ SpaceXAI
Keep the agents you've built. Endor Labs gives them the context, playbook, and people to run across every repo.
Harness Your Mechs · use the arrow keys